Day 81: the CSV comes back through one parser
Date: 2026-10-10 · Week 14 · Phase 5 Benchmark and optimize
What I added today
Day 80 finished the verdict on the row: claims_ok, claims_failed, and the subset of it the run could not measure, claims_unsound. Nothing read one of these files back except tests, and every one of them did csv.DictReader and .split("; ") by hand. The card sweep’s notebook would have been one more copy of that.
read_sweep(path) in graphbench.py is now the one place a sweep CSV turns back into rows:
- The verdict comes back typed.
claims_okis an int,claims_failedandclaims_unsoundare lists of notes, and an empty cell is[], not[""]. Every other column is left as the file had it. - A header it does not know is refused. A new
VERDICT_COLUMNSconstant names the three columns in the order they were appended. Every file this code has written ends in a prefix of it of length two or three. No verdict (a--coveragetable), half a verdict, a column moved, one skipped, or something after it: allValueError. So is an empty file. - A Day 76 file reads, and says what it does not know. It has no
claims_unsound, so that key comes backNone, not[]. - The subset is checked on the way in. An unsound note that is not also a failed note is a file the writer could not have produced, so it is refused.
tests/test_read_sweep.py has 14 pure tests: the constant matches what verdict_columns returns, a written row round-trips, a clean row is two empty lists, other columns stay strings in file order, rows keep file order, the real _delta claims round-trip at both sample floors, a Day 76 file gives None, five bad headers are refused, the subset check, and the empty file.
The toy sweep smoke gets one more test: its CSV reads back through read_sweep with the same loads in the same order, every claims_unsound an empty list, and held plus failed equal to 13 on every row.
Suite 2451 green (34 GPU-gated skips), ruff clean.
Why it matters
Two readers of one file drift. The tests and the notebook would each have had their own split. The day one of them learned about a new column and the other did not, a row would be graded one way in CI and another way on the plot. One parser makes that impossible.
"" and [""] are not the same row. "".split("; ") is a list with one empty note in it, so len(failed) on a clean row is 1 and held-over-total is off by one. Every hand-rolled reader in the tests remembered the if x guard. The next one has to remember it too, and the parser means nobody has to.
“Not recorded” is not “none”. A Day 76 file never said which failures were unmeasurable. Reading its missing column as an empty cell would make every old row look usable. None makes the notebook decide, on purpose.
What I learned
- Append-only columns make the header a version number. Because the verdict was only ever added to the end, “which day wrote this file” is just “how long a prefix of
VERDICT_COLUMNSdoes it end in”. No version field needed. - Refuse at the parser, not at the plot. A file with no verdict will happily plot. The only place that knows it should not is the code that reads the header.
- A writer invariant is worth checking on read. The subset property cannot fail for files
write_csvproduced, which is exactly why a file that breaks it is worth stopping on: something else touched it.
Diagram
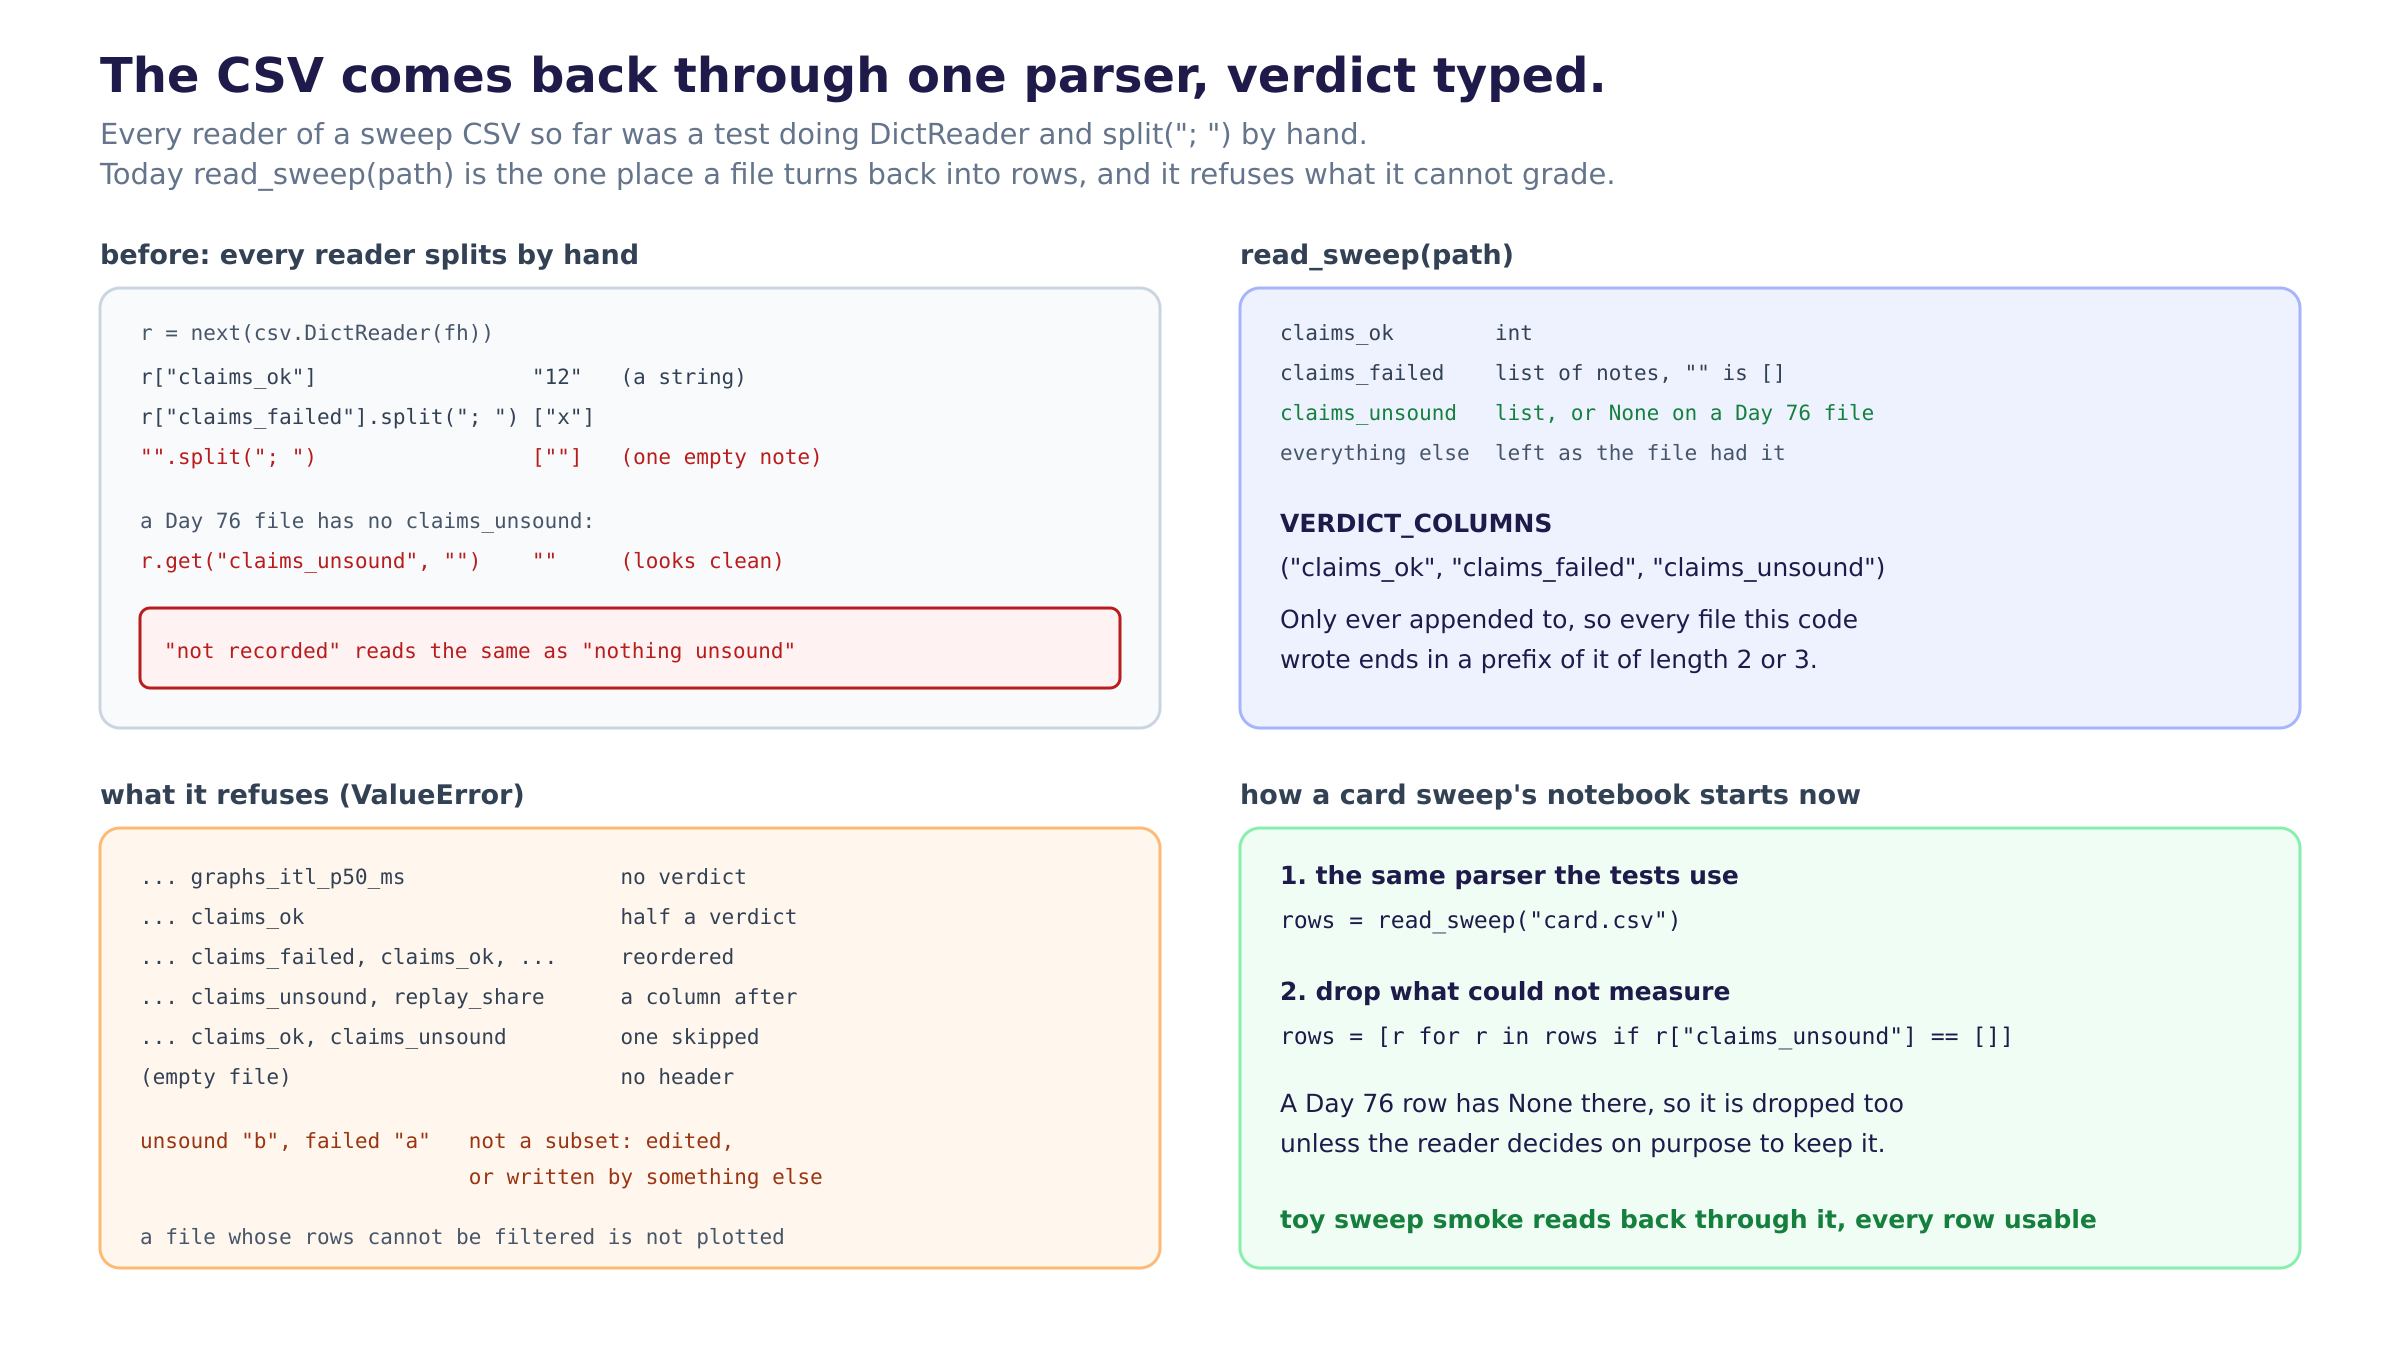
read-sweep.png. Top left: the hand-rolled reader and its two quiet mistakes. Top right: what read_sweep returns and the VERDICT_COLUMNS prefix rule. Bottom left: the headers and the edited row it refuses. Bottom right: how a card sweep’s notebook starts now.
Tomorrow
The sweep now writes, grades, and reads back. The rest of the columns still come back as strings, and a notebook converts units on its own. Next: have read_sweep know the numeric columns ArmDelta.row() writes (the _ms, _speedup, _tok_s and replay_share ones) and return them as floats, while leaving the split arm’s nullable cells as None rather than "", so the first plot of a card sweep is a plot and not a cleaning step.
The card run still comes first when hardware is booked.
Post angle
Day 81 of building an LLM inference engine from scratch. My benchmark CSV had one writer and a reader per test, each splitting by hand. "".split("; ") is [""], so every one of them had to remember a guard or count a clean row as one failure. Now there is one parser: typed verdict, a header it does not recognize is refused, and an old file’s missing column reads as None, not “clean”. 2451 green.